
32,97 €
Kostenloser Versand (Einschreiben Spanien, nur Festland) bis zum 31 . Dezember
Zahlung tc Akzeptiert Zahlung tcZustand des Artikels: Sehr gut (neu oder wie neu, ohne Gebrauchsspuren)
Print-on-Demand: Dieses Buch wird auf Nachfrage gedruckt. Die Lieferzeit hängt vom Druck ab, der beginnt, sobald der Käufer die Bestellung bezahlt hat.
Zahlung tc: zahle schnell und sicher per Karte oder Google Pay.
Autor: Devlin Nexley
Editorial: Devlin Nexley
Año: 03/10/2026
ISBN: 9782200177676
Encuadernación: Tapa blanda
Páginas: 220 pp.
Idioma: eng
EAN: 9782200177676
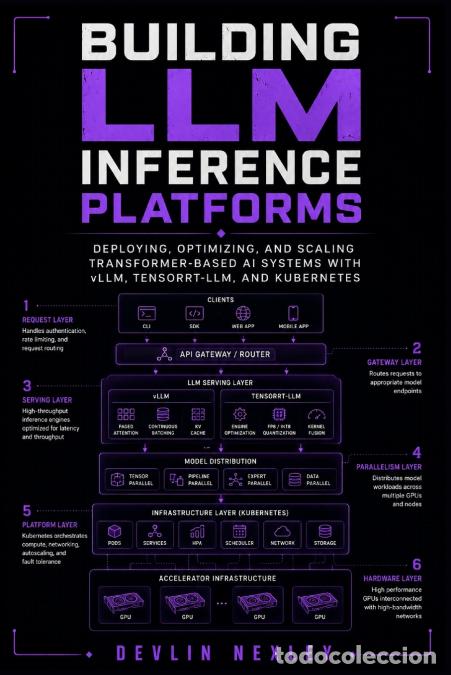
Modern large language model (LLM) systems are no longer simple model deployments-they are high-performance distributed inference infrastructures operating under strict latency, throughput, and memory constraints.
As organizations scale generative AI from prototypes to production systems, the real engineering challenge shifts from model training to inference architecture: how to serve transformer-based models efficiently across GPUs, manage KV-cache at scale, optimize decode latency, and sustain multi-tenant workloads under unpredictable traffic patterns.
This book provides a deep systems-level examination of LLM inference and serving infrastructure from the perspective of production engineering. It focuses on the internal mechanics of runtime execution, GPU utilization strategies, memory optimization, and distributed serving architectures used in modern AI platforms.
You will learn how real-world inference systems are designed, optimized, and operated at scale, including tradeoffs between latency, throughput, and cost in GPU-accelerated environments.
Key areas covered include transformer runtime behavior, KV-cache memory systems, continuous batching and scheduling, CUDA-level optimization techniques, quantization strategies, multi-GPU distributed inference, and Kubernetes-based serving architectures. The book also examines advanced topics such as speculative decoding, prefix caching, and emerging disaggregated inference models.
Rather than focusing on model training or high-level AI concepts, this book emphasizes the engineering reality of production inference systems: how requests are scheduled, how memory is managed under pressure, how GPUs are saturated efficiently, and how modern AI platforms achieve low-latency generation at scale.
It is intended for software engineers, infrastructure engineers, systems architects, and platform engineers working on or transitioning into AI infrastructure roles. A solid understanding of distributed systems, operating systems, or backend engineering is assumed.
By the end of this book, readers will understand how modern LLM serving stacks are built, why performance bottlenecks occur, and how to design scalable, efficient, and production-grade inference systems for large language models.
El envío se realizará en 48/72hrs.

Spanien (Guadalajara)
Verkäufer als professioneller Händler registriert.
Mehr Artikel von Devlin Nexley

Print-on-Demand Bücher
33,04 €
Zahlung tc

Print-on-Demand Bücher
39,15 €
Zahlung tc

Print-on-Demand Bücher
33,20 €
Zahlung tc

Print-on-Demand Bücher
33,10 €
Zahlung tc

Print-on-Demand Bücher
32,91 €
Zahlung tc

Print-on-Demand Bücher
33,20 €
Zahlung tc

Print-on-Demand Bücher
33,11 €
Zahlung tc

Print-on-Demand Bücher
33,04 €
Zahlung tc

Print-on-Demand Bücher
32,91 €
Zahlung tc

Print-on-Demand Bücher
39,24 €
Zahlung tc


 Español
 English
 Deutsch
 Français
 Português
 Italiano